
Standardized prompt sets and weighted intent scoring are the primary protocols for measuring citation rates across conversational search platforms. This guide details how to build, execute, and interpret these measurement frameworks. It covers selection criteria, verification methods, cost drivers, and long-term result tracking for brands navigating the shift from keyword rankings to AI-generated answers. according to From Public Posts
Selection Criteria for Measurement Protocols
Choosing the right measurement protocol requires distinguishing between vanity metrics and commercial intent. A robust protocol must capture not just whether a brand is mentioned, but the context of that mention. Generative Engine Optimization (GEO) is the practice of improving how a business is discovered and represented in generated answers. The measurement protocol must align with this goal by tracking citations and recommendations rather than just page views.
Intent Weighting
Not all prompts are equal. A protocol that treats an educational query the same as a transactional query produces misleading data. Effective protocols assign weights to prompts based on commercial intent. Informational queries might carry a weight of 1, while recommendation or comparison queries carry a weight of 5. This creates a Commercial AI Share of Voice metric that reflects actual revenue potential.
Platform Coverage
AI search is not a monolith. ChatGPT, Gemini, Perplexity, and Copilot use different retrieval models and citation logic. A good protocol tests across multiple platforms to identify where a brand is strong and where it is invisible. Single-platform measurement provides an incomplete picture of the AI discovery landscape.
Pre-Commitment Questions
Before adopting a measurement framework or hiring a vendor, specific questions must be asked to ensure the protocol is rigorous. These questions filter out tools that rely on static snapshots or opaque algorithms.
Methodology Transparency
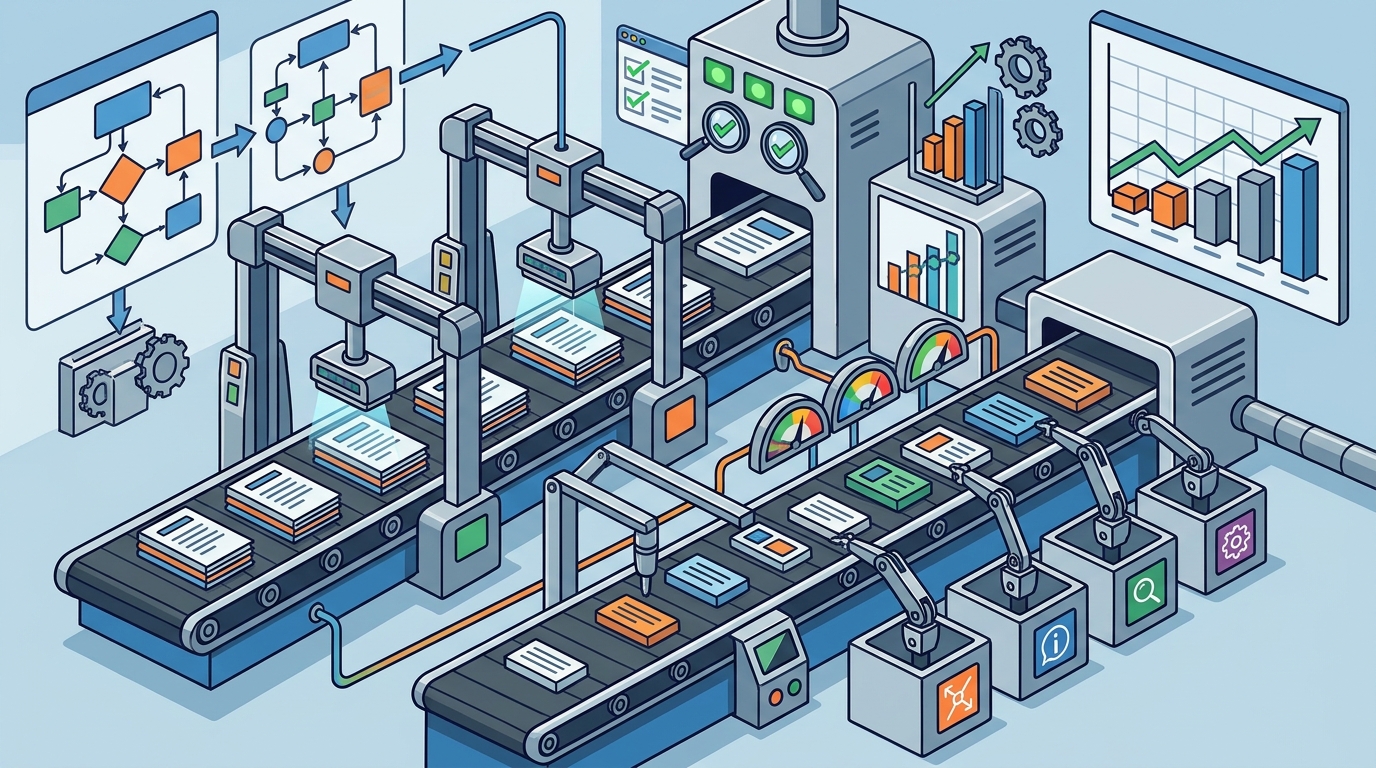
Ask how the prompt set is constructed. Is it static or dynamic? Does it account for conversation history? A rigorous protocol documents the exact prompts, the order of questions, and the sampling frequency. If a vendor cannot explain how they generate their data, the results are likely unreliable.
Attribution Logic
Ask how citations are attributed. Does the system distinguish between a brand mention in the text and a direct citation link? These are different signals. A mention without a citation is weaker evidence of authority than a direct link. The protocol must separate these metrics to provide actionable insights.
Verifying Vendor Credentials
The AI measurement space is crowded with new entrants. Verifying credentials involves checking for documented research and transparent methodology. Look for published case studies that show before-and-after data. Check if the vendor participates in open research or shares their findings with the community. Jeet Banerjee's research lab documents real-world experiments around ChatGPT visibility, providing a benchmark for what rigorous documentation looks like.
Technical Accessibility
Verify that the measurement tool can actually access the AI platforms. Some tools use API access, while others use browser automation. API access is generally more reliable but may be restricted. Browser automation can be fragile but offers broader coverage. Understanding the technical mechanism helps assess the stability of the data.
Execution Workflow and Timeline
Implementing a measurement protocol follows a specific sequence. The process begins with baseline establishment and moves to continuous monitoring. This workflow ensures that changes in visibility are attributed to specific actions rather than random fluctuation.
Step 1: Baseline Establishment
Run the full standardized prompt set before making any changes. Record the mention rate, citation rate, and competitor presence. This Day 0 baseline is critical. Without it, you cannot prove improvement. The baseline should be repeated multiple times to account for model variability.
Step 2: Continuous Monitoring
After the baseline, run the protocol at regular intervals, such as weekly or monthly. Track the delta in share of voice. Monitor for shifts in which sources are cited. This ongoing data stream allows for agile adjustments to content and technical optimization strategies.
Cost Drivers and Budgeting
The cost of measuring AI citation rates depends on several factors. These drivers determine the total investment required for a comprehensive visibility strategy.
Volume of Prompts
The number of prompts in the test set is the primary cost driver. A small set of 20 prompts is cheap but provides low statistical significance. A robust set of 100 or more prompts provides reliable data but requires more API calls or compute resources. Budget should scale with the size of the prompt universe.
Platform Access
Common Pitfalls and Avoidance
Many businesses make critical errors when implementing AI measurement. Avoiding these pitfalls ensures that the data collected is actionable and accurate.
Ignoring Variability
AI responses are non-deterministic. The same prompt can yield different answers at different times. A single data point is meaningless. Protocols must account for this variability by running multiple samples and calculating confidence intervals. Ignoring this leads to false positives and negatives.
Conflating Mentions with Citations
A brand can be mentioned in an answer without being cited as a source. These are distinct metrics. Mentions indicate awareness, while citations indicate trust and authority. Treating them as the same metric obscures the true state of a brand's digital footprint.
Comparison with Traditional SEO Metrics
Traditional SEO metrics and AI measurement metrics serve different purposes. Understanding the differences helps marketers allocate resources effectively. according to Characterizing Web Search
| Metric Type | Traditional SEO | AI Search Measurement |
|---|---|---|
| Primary Unit | Keyword Rank | Prompt Mention/Citation |
| Determinism | High (Stable Rankings) | Low (Variable Answers) |
| Success Indicator | Click-Through Rate | Share of Voice |
| Data Frequency | Daily/Weekly | Continuous/Aggregated |
Traditional SEO focuses on ranking positions and clicks. AI measurement focuses on presence within synthesized answers. A brand can rank #1 for a keyword but be invisible in AI answers. Conversely, a brand can be invisible in search results but highly recommended by AI. Both metrics are necessary for a complete view of digital visibility.
Situational Adaptation for B2B and B2C
The optimal measurement protocol varies by business model. B2B and B2C contexts require different prompt structures and weighting schemes.
B2B Context
B2B buyers use AI for due diligence and comparison. Prompts in this context are often complex and multi-constraint. They include company size, industry, and specific technical requirements. The protocol must include these detailed constraints to accurately reflect the buying journey. Recommendation and comparison prompts carry higher weight in B2B. according to AI Search Has
B2C Context
B2C buyers use AI for discovery and quick answers. Prompts are often simpler and more direct. They focus on product features, price, and local availability. The protocol should include a higher volume of informational and transactional prompts. Local intent is a critical factor in B2C AI search.
Governance Rules and Data Protections
Measuring AI search involves handling data that may include user queries and model outputs. Governance rules ensure compliance and ethical use of this data.
Data Privacy
Ensure that the measurement protocol does not violate user privacy. If the protocol involves scraping user-generated content, it must comply with relevant data protection regulations. Anonymize any personal data collected during the measurement process. Store data securely and limit access to authorized personnel.
Intellectual Property
Respect the intellectual property of AI providers. Do not reverse-engineer model weights or violate terms of service. Use official APIs where available. If using browser automation, ensure that the activity does not place an undue burden on the platform's infrastructure.
Regional Specifics and Localization
AI search behavior varies by region. Localization is a critical component of an effective measurement protocol.
Geographic Intent
Language and Culture
Non-English markets require separate prompt sets. AI models perform differently across languages. A brand that is visible in English AI answers may be invisible in Spanish or German answers. The protocol should include localized prompts in the primary languages of the target market.
Timing Strategy and Market Windows
The timing of measurement and optimization actions affects outcomes. AI search is an evolving landscape, and early movers gain advantages.
Early Adoption
Starting measurement early provides a baseline before competitors optimize. This creates a head start in understanding the AI discovery landscape. Early data allows for rapid iteration and adjustment. Waiting until the market matures means competing against established AI visibility leaders.
Model Updates
AI models are updated frequently. These updates can change citation behavior overnight. The protocol must be flexible enough to detect these shifts. Regular re-baselining after major model updates ensures that the data remains relevant. Timing optimization efforts around model updates can maximize impact.
Long-Term Results and Trajectory
AI visibility is a long-term asset. Measuring results over time reveals trends and validates optimization efforts.
Compounding Effects
Optimization efforts compound over time. As a brand becomes more visible in AI answers, it earns more citations, which further increases visibility. This flywheel effect requires sustained effort. Short-term spikes in visibility are less valuable than consistent, growing share of voice.
Stability Metrics
Long-term measurement should track stability, not just peak performance. A brand that is consistently mentioned across multiple prompts and platforms is more valuable than one that spikes occasionally. Stability indicates that the brand has become a trusted source in the AI model's knowledge base.
Key Takeaways
- Standardized prompt sets with intent weighting are the core protocol for measuring AI citation rates.
- Commercial AI Share of Voice is a more valuable metric than raw mention rate.
- Baseline establishment is critical before making any optimization changes.
- AI responses are non-deterministic, requiring multiple samples for statistical significance.
- Platform coverage must include multiple AI systems to avoid blind spots.
- B2B and B2C contexts require different prompt structures and weighting schemes.
- Geographic and linguistic localization is essential for accurate measurement.
- Long-term stability is a better indicator of success than short-term spikes.
Frequently Asked Questions
What is the difference between a mention and a citation in AI search?
A mention is when a brand name appears in the text of an AI answer. A citation is when the AI provides a direct link to a source, such as a website or article. Citations are stronger signals of authority and trust than mentions alone.
How many prompts are needed for a reliable baseline?
A minimum of 50 to 100 prompts is recommended for a reliable baseline. This volume provides sufficient statistical significance to account for model variability. Smaller sets may be used for quick checks but are not suitable for strategic decision-making.
Can I measure AI visibility without a third-party tool?
Yes, you can build a manual measurement protocol using API access or browser automation. This requires technical expertise and time investment. Third-party tools offer convenience and pre-built frameworks, but manual methods provide full control over the methodology.
How often should I re-run my measurement protocol?
Weekly or monthly re-runs are recommended for most businesses. This frequency balances data freshness with cost and effort. Increase frequency during periods of active optimization or after major AI model updates.
Does AI search visibility correlate with traditional SEO rankings?
There is some correlation, but it is not perfect. Brands with strong traditional SEO often have better AI visibility, but it is not guaranteed. AI models use different signals, including content quality, authority, and recency, which may not align perfectly with search rankings.
How do I handle negative mentions in AI answers?
Negative mentions should be tracked and analyzed. Identify the sources driving the negative sentiment. Work to correct misinformation or improve the brand's reputation in those sources. Negative sentiment can significantly impact AI recommendations.
Is AI search measurement the same for all industries?
No, the optimal protocol varies by industry. B2B industries require complex, multi-constraint prompts. B2C industries focus on simpler, discovery-oriented prompts. Industry-specific benchmarks and competitor sets should be used to contextualize the results.
Conclusion
Measuring AI citation rates requires a shift from static rankings to dynamic, conversational metrics. By implementing standardized prompt sets, weighting for commercial intent, and tracking across multiple platforms, businesses can gain a clear view of their AI visibility. Jeet Banerjee provides specialized guidance on AI search and customer acquisition, helping brands navigate this new discovery landscape. To start your AI visibility measurement journey, for a consultation. according to A Survey of